Zoom any paper to five levels: a hands-on guide to PaperFold
A paper asks you to hold its whole argument in your head while you read it one paragraph at a time. PaperFold holds the argument for you. PaperFold (chenxiachan/paperfold, Apache 2.0) is a local reading tool that opens any paper — arXiv, PubMed Central, bioRxiv, medRxiv, Wikipedia, a GitHub README, or your own Markdown file — and lets you zoom it through five levels: full text, brief, key, takeaway, and topic. It went from zero to nearly 100 GitHub stars in its first five days. This walkthrough takes it from a fresh clone to a paper you actually understand.
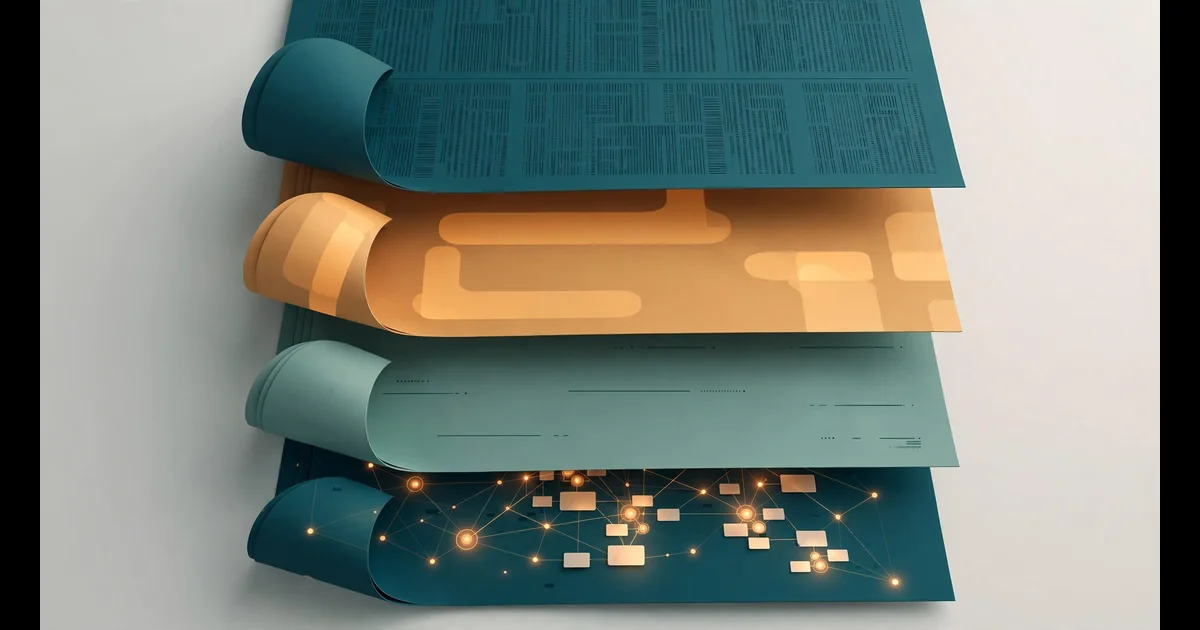
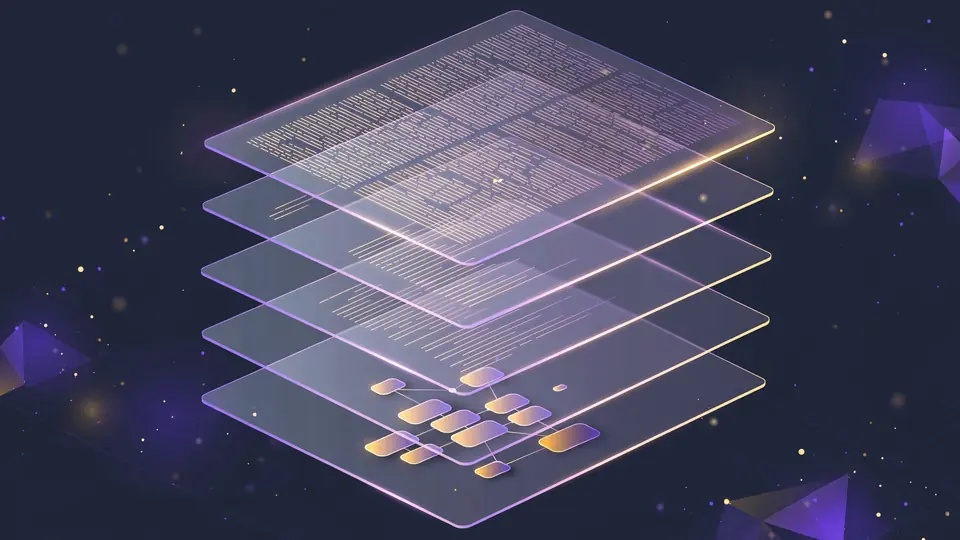
- The five levels: 1 — Full (the paragraph as written, the authors' own words); 2 — Brief (one to three key sentences, verbatim); 3 — Key (its point and the reason, AI's words); 4 — Takeaway (one line on the spine of the section); 5 — Topic (a few words; the paper becomes a map of section cards).
- The honesty mechanism is typographic: the authors' words are set in a serif, AI's in a sans serif, and every paragraph is colored by its role in the argument. Levels 1 and 2 are never paraphrased.
- Requires Python 3.9 or newer; install is git clone, pip install -r requirements.txt, then python3 -m adr serve — opening at http://localhost:3017 with no account, signup, or API key required.
- PaperFold auto-detects Claude Code, Codex, or Pi; a ChatGPT plan works through a one-click bridge (needs Node.js); OpenRouter one-click gives free models; or bring an API key (Anthropic, OpenAI, DeepSeek, Qwen, Zhipu GLM, Kimi, MiniMax, Google, Ollama, or any OpenAI-compatible endpoint).
- Sharing a folded paper: python3 -m adr export 2201.11903 writes one self-contained HTML file to out/2201.11903/ that opens anywhere without a server.
- License caveat from the README: PaperFold's Apache 2.0 license covers its code, not the papers — most arXiv papers allow reading but not redistribution.
The design is the whole pitch: AIHOT treats source curation as a knowledge-management problem. Six source types — RSS, web lists, JSON APIs, X accounts, WeChat public accounts, and content pushed in by your own scripts — are split into three tiers (official first-party, official accounts and quasi-official, media and individuals), each with its own admission threshold, and scrape frequency adjusts automatically with output. A story that survives pre-screening gets scored twice against the same rubric, gets a rewritten title and summary, and is clustered with other coverage of the same event: an LLM decides whether two stories are the same story, a follow-up, or two different things, with a second model able to re-review the decision (GROUP_REVIEW_MODEL). Heat is computed per event, not per article: each independent source counts once inside a 48-hour window, halving after 24 hours, so one outlet publishing ten takes on the same story does not move the needle — what ranks is what a lot of people are actually talking about.
What you’ll need
- Python 3.9 or newer. Per the README, the Python that macOS ships with works.
- A model you already have. PaperFold finds Claude Code, Codex, or Pi on its own; a ChatGPT plan works through a one-click bridge (needs Node.js); OpenRouter one-click gives you free models; or bring an API key — Anthropic, OpenAI, DeepSeek, Qwen, Zhipu GLM, Kimi, MiniMax, Google, Ollama, or any OpenAI-compatible endpoint.
- About 15 minutes.
Step 1 — see it before you install
Before touching your machine, open the PaperFold gallery: folded papers from different fields, a Wikipedia article, and a GitHub README, nothing to install. Pinch, ⌘-scroll, or drag the level bar to zoom; press 1 through 5 to jump levels. It shows you what it feels like when the tool holds the argument instead of you.
Step 2 — clone, install, serve
git clone https://github.com/chenxiachan/paperfold.git
cd paperfold
python3 -m pip install -r requirements.txt
python3 -m adr serve
Open http://localhost:3017 — the last command prints the address. That is the whole install: no account, no signup, no API key required yet.
Step 3 — connect a model
The first time it starts, PaperFold looks for a model you already have. If it finds none, the first page offers the ways in:
- Claude Code, Codex, or Pi — nothing to do. PaperFold finds it and uses it.
- A ChatGPT plan — click Use my ChatGPT plan. A small bridge starts on your computer and signs in with your account (needs Node.js).
- Nothing yet — click OpenRouter in one click. Authorize once, and free models are ready.
- An API key — Settings › Add provider: Anthropic, OpenAI, DeepSeek, Qwen, Zhipu GLM, Kimi, MiniMax, Google, Ollama, or any OpenAI-compatible endpoint.
Step 4 — fold your first paper
Paste the link or DOI of a paper on arXiv, PubMed Central, bioRxiv, or medRxiv, a Wikipedia article in any language, or a GitHub repository (its README) — or drag in a Markdown file of your own — and pick a language. Twelve are supported, translated sentence by sentence, with every formula as typeset. Then zoom. Every document gets the same five levels:
- 1 — Full. The paragraph as written. The authors’ own words.
- 2 — Brief. Its one to three key sentences, verbatim. Still the authors’ words.
- 3 — Key. Its point and the reason for it. AI’s words.
- 4 — Takeaway. One line on the spine of its section. AI’s words.
- 5 — Topic. A few words; the paper becomes a map of section cards. AI’s words.
The honesty mechanism is typographic: the authors’ words are set in a serif, AI’s in a sans serif, and every paragraph is colored by its role in the argument. At levels 1 and 2 you are reading exactly what the authors wrote — nothing is paraphrased.
Step 5 — work the reader
- Zoom. Pinch, or ⌘ / Ctrl + scroll, to zoom around the pointer. Keys
1–5jump levels; click a paragraph to open just that paragraph; click a figure to see it enlarged. - Read beside the original. The Original button at the top opens the paper’s PDF next to the text — from arXiv, PubMed Central, or bioRxiv — and shows each paragraph on its page as you read.
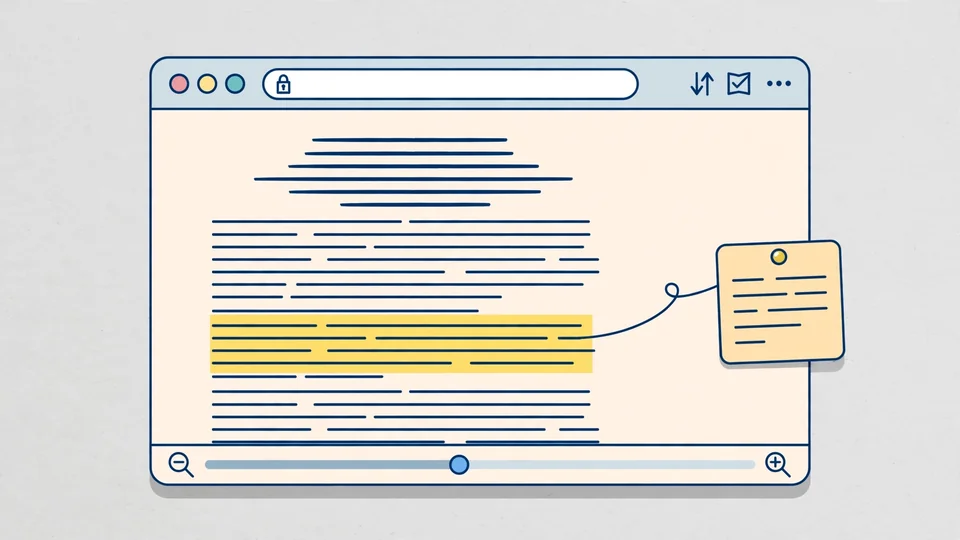
- Annotate. Select text to highlight, write a note in the margin, or ask about it. What you marked stays as you zoom out. Export to Obsidian, PDF, or JSON.
- Ask the paper. The Ask the paper button (bottom right) answers questions about the whole paper, and every answer cites the paragraphs it rests on — one click away.
- Switch languages. Press
Lfor the next language.
Step 6 — share a folded paper
python3 -m adr export 2201.11903This writes one self-contained HTML file to out/2201.11903/ that opens anywhere without a server — handy for sharing a reading with a colleague. One caveat the README is explicit about: PaperFold’s Apache 2.0 license covers its code, not the papers. The levels and translations stay under the license the paper’s authors chose (shown under every title); most arXiv papers allow reading but not redistribution, so share a page only when the license allows, as Creative Commons licenses do.
Step 7 (optional) — fold your agent’s replies too
Your agent writes more than you have time to read. TextFold — a Claude Code plugin from the same author — puts the five levels on every reply: press 5 for the answer in one sentence, 3 for the point of every paragraph, 1 for every word. It needs Claude Code 2.1.287 or later, in the terminal or in the Code tab of the Desktop app:
claude plugin marketplace add chenxiachan/paperfold
claude plugin install textfold@paperfold
What you built
A local zoomable-paper reader: any paper, README, or document at five zoom levels, evidence-cited Q&A over the full text, margin notes that travel with you as you zoom, sentence-by-sentence translation into twelve languages, and one-command export of a self-contained reading page — plus the same five levels for your Claude Code replies, if you want them.
Honest limitations
- arXiv papers need the HTML version. Most papers since late 2023 have one; older papers may not. A bioRxiv or medRxiv preprint, or a Wikipedia article in any language, is read from the site itself; anything else needs its open full text in Europe PMC.
- Zooming spends model tokens. Levels 3–5, translation, and Ask-the-paper answers are AI-written — run it on a model you already pay for, or a free OpenRouter one.
- It is five days old. The repo was created 2026-10-04; expect rough edges and a fast-moving README.
- Levels 3–5 are AI summaries, not the paper. The reader marks them typographically, and every answer cites its paragraphs — keep the citations open and skim level 1 for the sections that matter.
Still: reading a paper the old way means building the map in your head as you go. PaperFold hands you the map first and lets you unfold only the part you care about. For anything you read more than once — the papers that matter — that is a fair trade of fifteen minutes.