Stop parsing JSON from your LLM: typed decisions with real probabilities — hands-on with AnyJev
Every routing agent, triage bot, and moderation queue eventually does the same fragile dance: prompt the model to “reply in JSON,” regex the label out of the text, and retry when the output drifts. AnyJev takes the problem out of the generated text entirely. You hand the model a state and a typed question — a choice, a yes/no, or a score — and the answer is read as a probability distribution over the option labels, straight from the model’s next-token distribution. Nothing is generated, nothing is parsed.
- Open source (Apache-2.0) at nokia-applied-research/AnyJev; ~1,100 GitHub stars at the time of writing; from Nokia's applied research team.
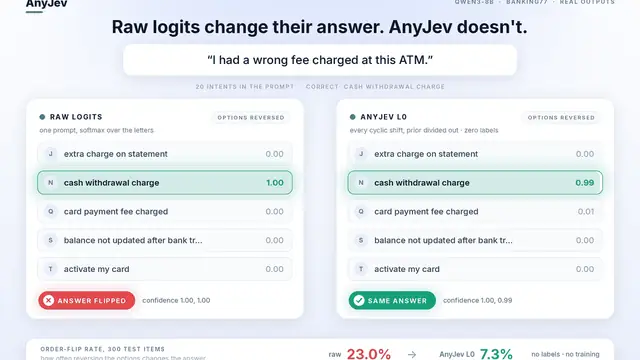
- Benchmark: on Qwen3-8B over 300 BANKING77 20-way intent items, AnyJev's L0 readout drops order-reversal flip rate from 23.0% to 7.3% and raises accuracy from 74.7% to 80.3%.
- Share of decisions confident enough to automate at ≤5% error jumps from 7.7% to 46.3%, with zero labels.
- Install: pip install anyjev; extras anyjev[client] (talking to a running vllm serve) or anyjev[vllm] (running vLLM in-process).
- Tacit checkpoints (1.7B to 9B on Hugging Face): self-distilled to give in one forward pass the answers the base model reaches when it reasons — no human labels, no teacher model.
- Requirements: Python 3.10+, any open causal LM for the training-free path, one GPU for the Tacit path, optional vLLM for the server path.
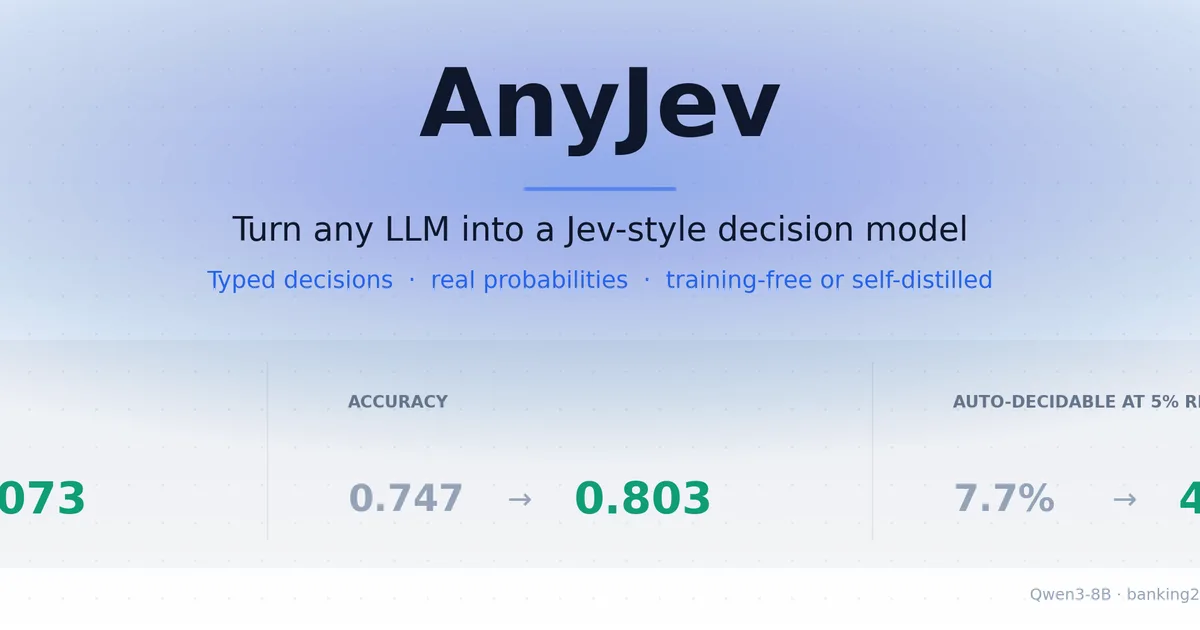
AnyJev (nokia-applied-research/AnyJev, ~1,100 GitHub stars, Apache-2.0 license) comes from Nokia’s applied research team, and its own numbers make the case. On Qwen3-8B over 300 BANKING77 20-way intent items: raw label logits flip their answer 23.0% of the time when you reverse the option order; AnyJev’s L0 readout drops that to 7.3%, accuracy rises from 74.7% to 80.3% — and the share of decisions confident enough to automate at ≤5% error jumps from 7.7% to 46.3%, with zero labels. Here is the full walkthrough, verified against the project’s own README and docs.
What you’ll need
- Python 3.10 or newer. Check with
python3 --version— the quickstart is pure Python. - One GPU for the Tacit path. The README’s example runs Tacit-9B on transformers with a single GPU.
- Any open causal LM for the training-free path. The benchmark used Qwen3-8B; checkpoints come from Hugging Face.
- Optional: vLLM. Only if you want the server path in step 5.
1. Install the package
The core library is one pip install:
pip install anyjevTwo extras cover the serving paths, and you install exactly one depending on your setup — anyjev[client] for talking to a running vllm serve, or anyjev[vllm] to run vLLM in the same process:
pip install "anyjev[client]"
# or:
pip install "anyjev[vllm]"
2. Make your first typed decision in one forward pass
The fastest route uses Tacit, AnyJev’s self-distilled checkpoints (1.7B to 9B on Hugging Face). They were trained to give, in one forward pass, the answers the base model reaches when it reasons — no human labels, no teacher model involved:
from anyjev import Tacit

tacit = Tacit.from_pretrained("morriszjm/Tacit-9B")          # transformers, one GPU
d = tacit.decide(state="Customer: my package was due last Monday and it still has not arrived.",
                 question="What does the customer want?",
                 options=["track_order", "cancel_order", "refund", "change_address"])
d["answer"], d["probs"], d["route"]    # an option, {option: probability}, "one_forward" or "cot"
kind defaults to "choice"; "yes_no" and "score" (options are ordered levels, lowest first) cover the other shapes. Batching is built in: decide_batch([...]) takes a list of such dicts. The route field tells you how the answer was read — "one_forward" or "cot" — so downstream code can check before it acts.
3. Go training-free on any open model
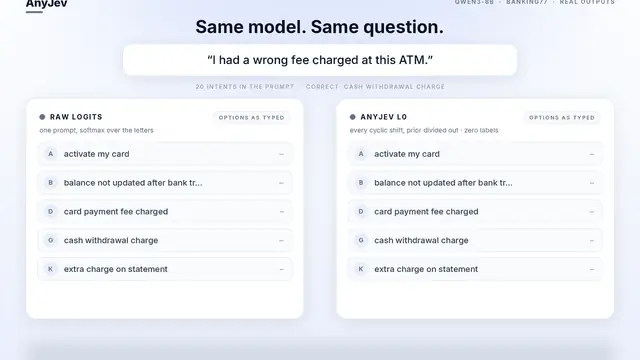
No Tacit checkpoint for your domain? The Decider reads the same typed decisions from any open causal LM, with no training and no labels. The default level is L0: the options are read in each of their rotations so every option sits at every position, the rotations are combined in log space, and the model’s label prior is divided out — all estimated without a single label. That is what kills the 23% order-flip rate:
from anyjev import Decider, Question
from anyjev.backends.hf import HFBackend          # or anyjev.backends.vllm.VLLMBackend(url, model)

d = Decider(HFBackend("Qwen/Qwen3-8B"))           # level="L0" by default
route = Question.choice("Which team should handle this?",
                        ["billing", "technical", "sales", "other"], name="route")
r = d.decide("My card was charged twice for one order.", [route])["route"]
r.distribution, r.level                           # {option: probability}, "L0"
Enforcement comes free: decide(..., require="L0") raises LevelError when a decision lands below the asked level, so a degraded readout can’t silently become an automated action. Every decision also records diagnostics — answer_mass (the probability the model put on the label tokens at all; a low value means the prompt did not land), order_flip_raw, permutations, and the prior method used.
4. Send only the hard calls to reasoning — with a cap
Reasoning helps the close calls and wastes budget on the easy ones. The adaptive mode sends a decision back through with thinking turned on only when the log-probability gap between the top two options falls below tau. The answer is still read as a label distribution, so it cannot fail to parse — and a hard cap bounds the cost:
tacit = Tacit.from_pretrained("morriszjm/Tacit-9B", adaptive=True, tau=0.5, max_cot_share=0.2, cot_window=1000)tau(default 0.5): low confidence means the top-two gap is below this.max_cot_share(default 0.2): at most this share of the lastcot_windowdecisions escalates, however hard the traffic gets.Noneremoves the cap.cot_max_tokens(default 8192): the reasoning budget of one decision.
Every escalation is reported (route == "cot", with the first pass kept), and tacit.stats counts them. The training-free Decider has its own budget version: Decider(adaptive_shifts=True, canonical_order=True) reads rotations until the leader is far enough ahead, and calibrate_adaptive sets that threshold against the full-cycle answer — no labels — at a stated disagreement rate. The project reports that at a certified 1% disagreement it read 7.2 rotations instead of 18: 2.2× the decisions per second on vLLM, accuracy unchanged.
5. Serve it as a decision endpoint
When one cap has to serve many clients, AnyJev ships a gateway. Point a stock vllm serve at a Tacit checkpoint, then run the server module in front of it:
pip install "anyjev[client]"
vllm serve morriszjm/Tacit-9B --host 127.0.0.1 --port 8000
python -m anyjev.serve --model morriszjm/Tacit-9B --upstream http://127.0.0.1:8000 --adaptive --port 8100
curl -s 127.0.0.1:8100/v1/decide -H 'Content-Type: application/json' \
-d '{"state": "Customer: my package has not arrived.", "question": "What does the customer want?", "options": ["track_order", "refund"]}'POST /v1/decide takes one decision or {"items": [...]}; GET /v1/stats reports the escalation share across clients. Note the security posture stated in the README: the gateway listens on 127.0.0.1 and has no authentication of its own — keep it on loopback or put your own auth in front.
What you built
A typed-decision service with real probabilities. Instead of prompting for JSON and parsing the reply, you ask choice, yes_no, or score questions and get back an option, a probability distribution, and a readout level — plus the diagnostics (answer_mass, rotation counts, prior method) to know when to trust it. Escalation is capped and reported, so the “let it think harder” path can’t eat your budget silently.
Honest limitations
- Open models only. The
Deciderbackends are HF transformers and vLLM for open causal LMs — this is not a wrapper for API models, and Tacit checkpoints are a 1.7B–9B family on Hugging Face. - Young project. The technical report (arXiv 2610.00831) dates to October 2026 and the API may shift: note that the label-trained levels
L1andL2were removed in 0.3.0 (they remain inanyjev==0.2.0), so older write-ups may reference them. - Benchmarks are intent-classification shaped. The headline numbers are BANKING77 20-way; your domain may behave differently —
answer_masstells you whether the prompt landed before you automate anything. - The batch prior assumes balance. The default label prior is estimated from the batch being decided; if one option dominates the batch, it costs accuracy. Switch to
prior="content_free"orprior="none"when that’s the case. - No auth on the gateway. Bind to 127.0.0.1 or add your own proxy — the project is explicit that authentication is yours to add.
- Docs to bookmark: the GitHub repo (README has the full quickstart), docs/levels.md (what each readout level promises), the Tacit checkpoint collection, and the technical report (PDF).