Strip the AI accent from your Japanese drafts: a hands-on tour of yomiyasu
There is a specific smell to AI-written Japanese. Not wrong grammar — a sheen of dead metaphors, boldface on every other sentence, sentences whose subjects quietly went missing. “アクセシビリティが静かに壊れます” (accessibility silently breaks), “時間を溶かさない” (not melting time). Nobody would write that. Everybody’s model does. yomiyasu (よみやす, “easy to read”) is an open-source agent skill — MIT, built by ALGO ARTIS, roughly 1,850 GitHub stars as of October 2026 — that fixes this at the structural level instead of swapping banned words. It repairs missing subjects, deflates metaphors into plain operations, and thins out the bold-and-bullet inflation, while refusing to add anything that wasn’t in your draft. This tutorial: install it in Claude Code, run it on a real AI-written draft, then audit the result with its built-in lint and diff tools.
- yomiyasu is an open-source agent skill (MIT, built by ALGO ARTIS) with roughly 1,850 GitHub stars as of October 2026, designed for practical writing: tech articles, spec/design documents, PR write-ups, internal reports.
- It repairs at the structural level: missing subjects, metaphors deflated into plain operations, bold-and-bullet inflation thinned out — while keeping claims, emphasis and certainty exactly as strong as the original.
- Install: npx skills add nanaism/yomiyasu (recommended); or gh skill install nanaism/yomiyasu; or as a Claude Code plugin (/plugin marketplace add nanaism/yomiyasu, /plugin install yomiyasu@yomiyasu). Restart Claude Code after installing.
- Usage: paste your draft and write one line — この文章を読みやすくして。 — the skill detects the domain (tech, business, essay) automatically; pin it with '技術記事向けに' or 'ドメイン tech'.
- Seven named transformation principles: subject–predicate check; sentence role and register; de-personify tools and concepts; flatten metaphors ('壊れる', '効く', '溶かす' → what literally happens); trim openers only when free; add nothing (no new actors, causes, numbers, feelings); sentence rhythm (30-45 characters per sentence, 0-2 commas).
- Bundled lint and diff checkers need only Python stdlib: git clone https://github.com/nanaism/yomiyasu.git, then python3 scripts/yomiyasu_lint.py my-draft.md — scores the text out of 100 on metaphor verbs, bold/bullet inflation, emoji, trailing colons and more.
What you’ll need
- Claude Code, Codex, or Cursor — yomiyasu installs as a skill (Claude Code, Codex) or a plugin (Claude Code marketplace); the ZIP route works for Claude.ai’s web skills too.
- A Japanese draft written by an AI — a technical post, a design doc, a PR description. The skill is designed for practical writing: tech articles, spec/design documents, PR write-ups, internal reports.
- Python 3 (stdlib only) — for the bundled lint and diff checkers. No pip packages required.
One honest note before we start: the skill, its docs, and its examples are written in Japanese, with English summaries. The commands and output shown here are real; the Japanese quotations are reproduced from the project’s own README examples.
Step 1 — install the skill
The project’s recommended route is one command:
npx skills add nanaism/yomiyasuThat drops the skill definition into your agent’s config directory. Updating later is just as short:
npx skills update yomiyasuTwo more routes exist, both documented in the README. If you’re a GitHub CLI person:
gh skill install nanaism/yomiyasu yomiyasuAnd the whole project is shipped as a single SKILL.md under skills/yomiyasu/, so Claude Code users can also register it as a plugin:
/plugin marketplace add nanaism/yomiyasu
/plugin install yomiyasu@yomiyasu
Restart Claude Code after installing. If you use other Japanese proofreading skills alongside it, the README warns the instructions can conflict and the output can degrade — disable the similar ones while you work.
Step 2 — give it a sloppy draft
The usage is deliberately boring. Paste your draft into the chat and write one line:
この文章を読みやすくして。That’s it — no flags, no templates. The skill detects the domain (technical article, business document, essay) from the content. If you want to pin it, say so in plain words — “技術記事向けに” — or explicitly: “ドメイン tech”. The three domains are:
- tech — tech blogs and code explanations; restores procedures and mechanics, keeps bullets down.
- business — specs, PR text, proposals; strips metaphors and pins down boundary conditions and who is responsible for what.
- essay — personal blogs and notes; avoids grand moralizing, keeps honest feeling.
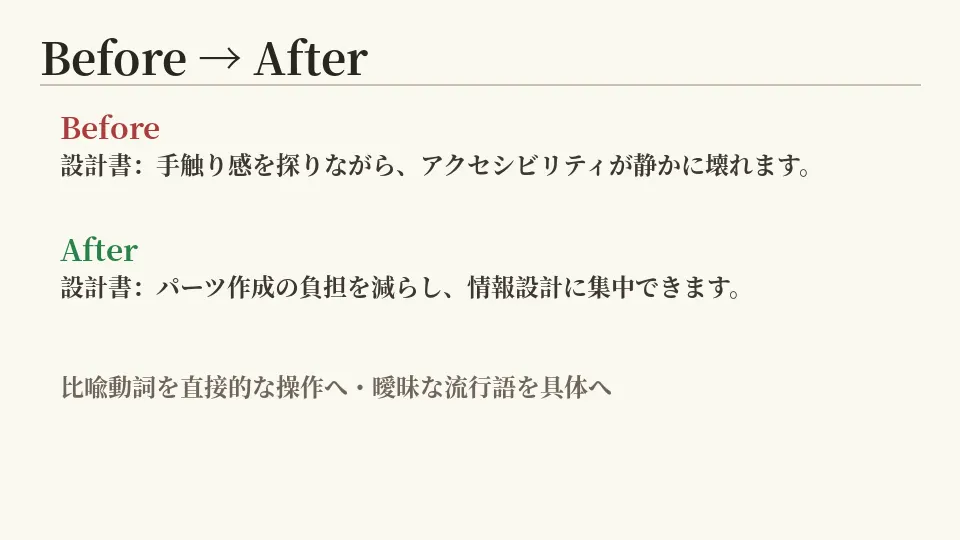
To see what “structural” actually means, here is the project’s own example — a spec-explanation Before/After, reproduced verbatim:
# Before
設計書:画面ごとに手触り感を探りながらパーツを作っていました。しかし、
片方だけを見て画面を作ると、もう片方のアクセシビリティが**静かに壊れます**。

# After
設計書:ボタンや入力欄などのUIパーツを一から作成する負担を減らし、
画面全体の情報設計に集中することにあります。
Notice what changed and what didn’t. The metaphor verbs (“quietly breaks”) and the vague buzzwords (“hand feel”) became concrete operations. The boldface — which the original sprinkled for emphasis — is gone, and the list is folded back into running prose. The claims stayed the same; only the readability changed.
Step 3 — read the change notes, not just the output
Here’s the habit that makes the skill trustworthy: it treats readability as seven named transformation principles, not vibes. Skimming them explains nearly every edit it makes:
- Subject–predicate check. Map every subject to its verb, every modifier to what it modifies — and fill in a missing actor only when the source text actually determines it.
- Sentence role and register. Keep the distinction between explanation, request, advice, and plans; fix only endings that don’t fit their role. Don’t switch plain style to polite style just because it’s a technical article.
- De-personify. Tools and concepts don’t have feelings; keep the non-human subjects that describe objective behavior.
- Flatten metaphors. “壊れる” (breaks), “効く” (works/cures), “溶かす” (melts) — replaced with what literally happens, without moving the subject or object.
- Trim openers only when free. An intro is cut only if the claim keeps its weight without it; evaluations and needed contrasts stay.
- Add nothing. Keep claims, emphasis, and certainty exactly as strong as the original — no new actors, causes, numbers, or feelings. Uncertain parts stay marked as uncertain, with the review note placed after the body, not in it.
- Sentence rhythm. Aim for 30–45 characters per sentence, 0–2 commas; don’t strip punctuation from text that already reads well.
Principle 6 is the one that separates this from a generic “make it sound better” prompt: it may reorganize how a sentence reads, but it is contractually barred from making the draft smarter than it was.
Step 4 — lint the draft for AI fingerprints
The repo ships two Python checkers that need nothing but the stdlib. Clone the repo and point the linter at your file:
git clone https://github.com/nanaism/yomiyasu.git
cd yomiyasu
python3 scripts/yomiyasu_lint.py my-draft.md
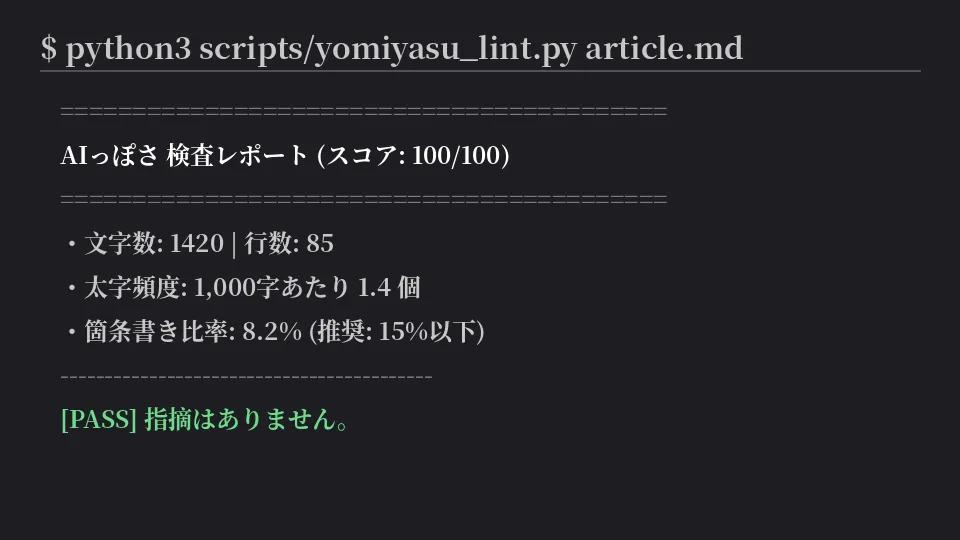
It scores the text out of 100 and checks for the usual suspects: metaphor verbs, bold/bullet inflation, emoji, trailing colons, repeated sentence endings, and bold markup that won’t even render because of surrounding Japanese punctuation. A clean report looks like this (from the README):
============================================================
AIっぽさ 検査レポート (スコア: 100/100)
============================================================
・文字数: 1420 | 行数: 85
・太字頻度: 1,000字あたり 1.4 個 (推奨: 2.0以下 / 警告: 3.0超)
・箇条書き比率: 8.2% (推奨: 15%以下 / 警告: 25%超)
------------------------------------------------------------
[PASS] 設定された検査ルールによる指摘はありません。
Two flags matter in practice. --strict exits non-zero on any warning — built for CI and git hooks — and --json gives you machine-readable output. The project is explicit about what the tool is not: not a full renderer, not a guarantee of naturalness, and a [PASS] means only “no rule fired,” not “this is good writing.” Don’t mechanically zero out the warnings; read each one against the sentence.
Step 5 — diff the before and after for meaning drift
The second checker compares your original and the edited version and hunts for unintended changes:
python3 scripts/yomiyasu_diff.py original.md edited.md --stance=説明It reports word gains and losses, shifts in sentence endings (polite vs. plain), changes in the sentence’s “stance” — is it recommending, stating a rule, or explaining? — and whether bold markup will actually render. The --stance value is the document’s role (説明 = explanatory); there’s also an --endings mode that just shows the distribution of endings. The README’s caveat applies here too: it surfaces candidates for review. It does not automatically decide the meaning is unchanged — that judgment is yours, which is exactly the point of running it.
What you built
A readable-Japanese pipeline you can run from your editor. You installed an MIT-licensed agent skill (nanaism/yomiyasu) that repairs AI-written Japanese at the sentence-structure level, learned to pin its domain (tech/business/essay), and added two stdlib-only guardrails: yomiyasu_lint.py to catch AI fingerprints before publishing, and yomiyasu_diff.py to make sure the rewrite didn’t quietly change what you meant. No model API, no subscription, nothing leaves your machine unless you want it to.
Honest limitations
- Japanese only — and Japanese-language agents. The skill, its docs, and its verification corpus are Japanese. It’s built for people who write in Japanese or manage Japanese drafts; the tutorial above works, but the ecosystem around it doesn’t translate itself.
- It can’t fix what isn’t there. If the draft’s argument is hollow, you get hollow prose that reads smoothly. Principle 6 cuts both ways: it never adds substance, and it never will.
- The linter’s [PASS] is not an editor. The project says it plainly: a clean score means no rule fired, not that the text is natural or correct in every viewer. Over-tuning to zero warnings is the same disease it diagnoses.
- Don’t stack similar skills. The README warns that running other Japanese proofreading skills alongside it makes the instructions fight and the output worse. Pick one.
- It’s young. Created 2026-09-30, first releases arriving in October (v1.1.1 on 2026-10-09). The README documents verification data under
evals/and regression fixtures intests/, but a month-old project is a month-old project — read the diff, always.
The uncomfortable part: much of what this skill fixes — the metaphor verbs, the breathless boldface, the sentences that gesture instead of saying — is in your writing too if you prompt sloppily. The linter makes a decent mirror for that. Run it on your own prompt output before you blame the model.