Route tickets, pick tools, and score outputs in 115ms: hands-on with Strands Decider
Most agent decisions don't need an essay — they need a choice. Which team owns this ticket? Should the agent call the refund tool? Is this message urgent? Today those questions go through a full-size LLM with JSON parsing on the other side: slow, expensive, and brittle the moment the model gets chatty. Strands Decider (strands-labs/strands-decider, 503 GitHub stars, Apache-2.0) is a 1.9B-parameter decision model built for exactly this: it picks between options, answers yes/no, or rates on a scale — no text generation at all — with a calibrated confidence on every answer. Median answer time on an RTX 3090 is 115 milliseconds.
- Open source (Apache-2.0) at strands-labs/strands-decider, with 503 GitHub stars.
- Built on a Qwen3.5-2B-Base torso with the language-modeling head replaced by a ~1-million-parameter pointer head; one forward pass, no decoding loop.
- Torso adapted with a rank-16 LoRA adapter; the head runs in fp32 and carries no per-option parameters, so label sets are defined per request.
- Median answer time 115 ms on an RTX 3090 reference; runs on Apple silicon (MPS, or --device mlx for 1.4–1.6x faster), CPU, or CUDA GPU.
- Install is pip install strands-decider; checkpoints are pulled from Hugging Face on first use.
- Designed for "system one" decisions: ticket routing, tool selection, urgency scoring — the fast rote questions, leaving hard reasoning to the big LLM.
It comes from Strands Labs, the experimental arm of Strands Agents, and rides the current wave of "system one" decision models: small models that answer the fast, rote questions so your big LLM can spend its tokens on the hard ones. Under the hood it's a Qwen3.5-2B-Base torso with the language-modeling head thrown away, replaced by a ~1-million-parameter pointer head that scores each option against the model's answer position. One forward pass, no decoding loop; the torso is adapted with a rank-16 LoRA adapter and the head runs in fp32. Because the head carries no per-option parameters, your label sets are defined by the request — never baked into the weights.
What you’ll need
- Python 3 and pip.
pip install strands-decideris the whole install. The 1.9B checkpoint runs on an Apple-silicon Mac (MPS, or--device mlxfor 1.4–1.6× faster than MPS), on CPU, or on a CUDA GPU — the 115 ms figure is the RTX 3090 reference. - A few GB of disk for the 1.9B-parameter checkpoint, pulled from Hugging Face on first use.
- No training, no labels. You ask questions in plain text; the model answers them. That is the entire point.
1. Install and ask your first choice question
Install the CLI and triage a support ticket — a classic choice question, straight from the project's README:
pip install strands-decider
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v21 \
  --state "Help! My payouts have been failing for 3 days! " \
  --choice "Which team should handle this?=billing,sales,retail"
Example output from the project:
choice_0 -> billing (confidence 0.835)

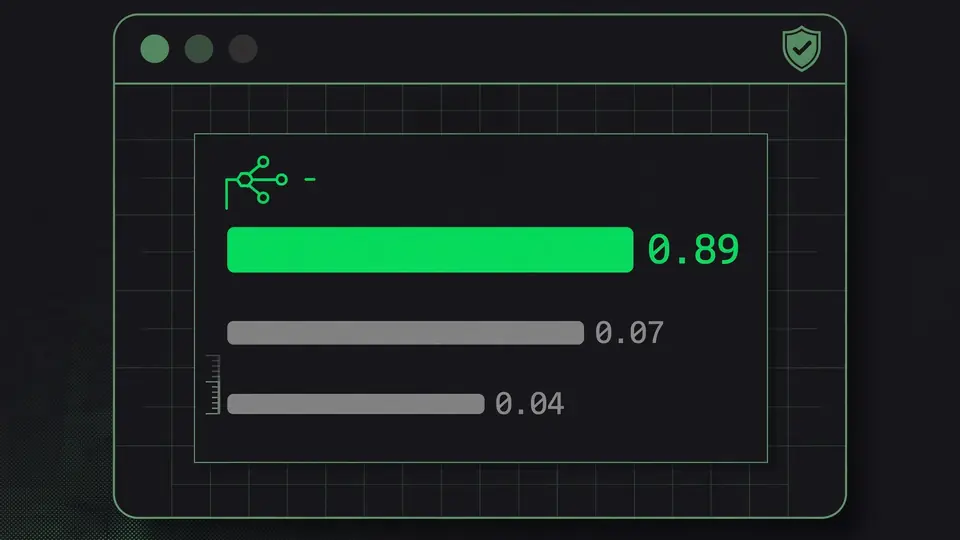
  billing                  0.890
  sales                    0.056
  retail                   0.054
You get the pick, a confidence number, and a distribution over every option. That confidence is the feature: on short classification tasks it has never seen, answers at a confidence of 0.9 or more are right about 95% of the time (evaluation/results.md in the repo). Below that, the README says to confirm or ask a person. In an agent, this maps directly to a policy: act above your threshold, escalate below it.
2. Ask a yes/no question with noul
The second question type is a yes/no — called noul, measuring how strongly the model leans "yes":
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v21 \
  --state "Help! My payouts have been failing for 3 days! " \
  --noul "Does this convey urgency?"
noul_0 noul = 0.875Closer to 1 leans more toward yes. This is your guardrail primitive: policy classification, grounding checks, "should a human see this before it goes out."
3. Score on an ordered rubric
The third type rates things on a scale — useful for evaluations and prioritization:
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v21 \
  --state "Help! My payouts have been failing for 3 days! " \
  --score "How frustrated is the writer?=calm,frustrated,depressed"
score_0 score = 1.07 (confidence 0.602)
0: calm 0.140
1: frustrated 0.648
2: depressed 0.2124. Batch all three in one call
The state is read once and each question adds only its own tokens, so combining questions is cheap:
strands-decider ask StrandsAgents/strands-decider-2B-hobson-v21 \
  --state "Help! My payouts have been failing for 3 days! " \
  --choice "Which team should handle this?=billing,sales,retail" \
  --noul "Does this convey urgency?" \
  --score "How frustrated is the writer?=calm,frustrated,depressed"
You now have routing, urgency, and frustration in a single batched call — the three things a triage loop needs before it decides what to do.
5. Serve it over HTTP for your agent
For real wiring, run it as a server — the README's own pattern for putting decisions inside agentic workflows:
strands-decider serve StrandsAgents/strands-decider-2B-hobson-v21 --port 8000curl -s localhost:8000/v1/systemone \
-H 'content-type: application/json' \
-d '{
"state": "Help! My payouts have been failing for 3 days!",
"questions": {
"is_urgent": {"type": "noul", "instructions": "Does this convey urgency?"}
}
}'The response carries the model name, the typed answers, token usage (note: one output token — nothing was generated), and the latency in milliseconds. From here the README's suggested uses read like an agentic-systems checklist: model routing (pick the right LLM for a task), tool selection (which tool the agent should call next), argument checking (verify a tool call before it runs), triage, guardrails, evaluations, and hybrid agents — the big LLM makes the hard decisions, the decider makes the rote ones. The repo ships a worked examples/strands/ example that gates a tool call with a before_tool_call intervention.
What you built
A ticket-triage decision pipeline with five moving parts: an install, a choice question that routes a ticket to billing with 0.89 of the distribution mass, a yes/no urgency check, a frustration score, all three batched into one call, and an HTTP endpoint your agent can query at ~115 ms a question. No JSON parsing, no prompt-format fragility, and a confidence number you can turn into an escalation policy.
Honest limitations
- It cannot explain itself. A decision model never generates text, so you get the pick and the confidence but no rationale. If a decision needs a paper trail, pair it with an LLM — the hybrid-agents pattern is in the README for exactly this reason.
- Calibration holds where it was measured. The 95%-at-0.9 figure is for short classification tasks the model has never seen; on long, messy, or domain-specific input, recalibrate before trusting the number. On JevBench v1 the current v21 scores 0.762 accuracy (176 of 231) with expected calibration error 0.064 — and the hard tier sits at 0.550. Hard questions still beat it.
- Read the README's own caveats. The v19/v21 comparison columns are two single runs, not a measured gain; run-to-run standard deviation is 3.2 tasks, so treat any gap under about 10 tasks as unresolved.
- It's early. Sixteen commits from an experimental lab (Strands Labs, created September 29, 2026) — expect the API to move. The vision variant (
--vision) needs the[vision]extra and transformers 5.18 or later; I left it out of this walkthrough deliberately.
Still: for the rote decisions inside every agent — routing, tool selection, guardrails — a 2B model that answers in 115 ms with a confidence you can budget against is the cheapest upgrade on the board.